

Product Information
What is W.a.l.t video diffusion?
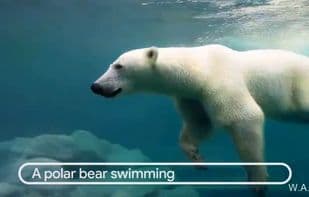
W.A.L.T is a transformer-based approach for film and video generation through diffusion modeling. It employs a causal encoder to compress images and videos into a unified latent space, along with a windowed attention architecture for joint spatial and spatiotemporal generative modeling.
This design enables state-of-the-art performance on video (UCF-101 and Kinetics-600) and image (ImageNet) generation benchmarks without classifier-free guidance. Additionally, we utilize a three-stage model cascade for text-to-video generation, producing 512 x 896 resolution videos at 8 frames per second.
How to use W.a.l.t video diffusion?
W.A.L.T Video Diffusion is a Transformer-based diffusion model method focused on generating realistic videos. By unifying images and videos into a latent space and leveraging a windowed attention architecture, it achieves high-quality video and image generation.
Core Functions of W.a.l.t video diffusion
Image-to-Image Generation, AI-Driven
Usage Scenarios of W.a.l.t video diffusion
- Text-to-video generation
- Image-to-Video Generation
- Generate videos with consistent 3D camera movements
- Realistic video generation
- Image Generation
Common Questions about W.a.l.t video diffusion
What does W.A.L.T Video Diffusion do?
How do I use W.A.L.T Video Diffusion?
What are the core features of W.A.L.T Video Diffusion?
What are the use cases for W.A.L.T Video Diffusion?