

Product Information
What is Dia tts model?
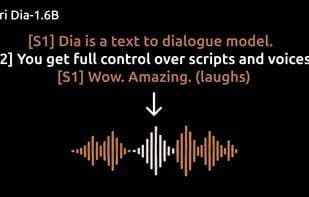
DIA is a 1.6B-parameter text-to-speech model developed by NARI Labs.
DIA generates highly realistic dialogue directly from transcripts. You can adjust the output based on audio, enabling control over emotion and tone. The model can also produce non-verbal communication, such as laughter, coughing, throat clearing, and more.
To accelerate research, we are providing validated model checkpoints and inference code. The model weights are hosted on Hugging Face. Currently, the model supports only English.
How to use Dia tts model?
Dia TTS Model is a text-to-speech model created by Nari Labs, capable of generating ultra-realistic conversations directly from text, supporting emotion and tone control via audio, and generating non-verbal communication.
Core Functions of Dia tts model
AI voice cloning
Text-to-Speech
Python-Based
Usage Scenarios of Dia tts model
- Generate ultra-realistic dialogue content
- Add emotion and tone control to voice output
- Incorporate non-verbal communication (e.g., laughter, coughing, throat clearing) into conversations
- Provide researchers with pre-trained models and inference code to accelerate research
Common Questions about Dia tts model
What does Dia TTS Model do?
How do I use Dia TTS Model?
What are the core features of Dia TTS Model?
What are the use cases for Dia TTS Model?