

Product Information
What is Vibevoice?
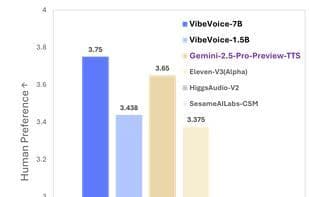
VibeVoice is an innovative framework designed to generate expressive, long-form, multi-speaker conversational audio (such as podcasts) from text. It addresses significant challenges faced by traditional text-to-speech (TTS) systems, particularly in scalability, speaker consistency, and natural transitions. The core innovation of VibeVoice lies in its use of continuous speech tokens (acoustic and semantic) operating at an ultra-low frame rate of 7.5 Hz. These primers effectively preserve audio fidelity while significantly enhancing computational efficiency for processing lengthy sequences. VibeVoice employs a next-step diffusion framework, leveraging large language models (LLMs) to understand textual context and dialogue flow, along with a diffusion head to generate high-fidelity acoustic details efficiently.
The model can synthesize up to 90 minutes of speech with as many as four distinct speakers, surpassing the typical 1-2 speaker limitations of many prior models.
How to use Vibevoice?
VibeVoice is a novel framework generating expressive, long-form, multi-speaker conversational audio (e.g., podcasts) from text, addressing scalability, speaker consistency, and natural turn-taking challenges in traditional text-to-speech systems.
Core Functions of Vibevoice
Text-to-speech, AI-powered
Usage Scenarios of Vibevoice
- Generate long-form conversational audio like podcasts from text.
- Scenarios requiring multi-speaker voice synthesis.
- Synthesize voice content up to 90 minutes long.
- Generate dialogues with up to 4 different speakers.
Common Questions about Vibevoice
What does VibeVoice do?
How do I use VibeVoice?
What are VibeVoice's core features?
What are VibeVoice's use cases?